I built Pingjobs around Jev
I built Pingjobs around Jev.
The idea is fairly simple. Tell Ping what work you want to do next, what a role must offer, and what you want to avoid. It checks employer postings against that brief and shows which roles may fit, alongside the original evidence.
Jev is what made this version of Pingjobs possible for me. It gives me a way to turn messy descriptions of work into focused judgements that the rest of the product can use.
I think the obvious LLM approaches would have produced a sub-par version of what I wanted to build. A prompt that picks jobs and writes convincing explanations is easy to imagine. But the product needs to preserve the difference between work that fits, requirements that pass, and facts nobody has confirmed.
The job title tells you very little
Take someone looking for a senior product design role.
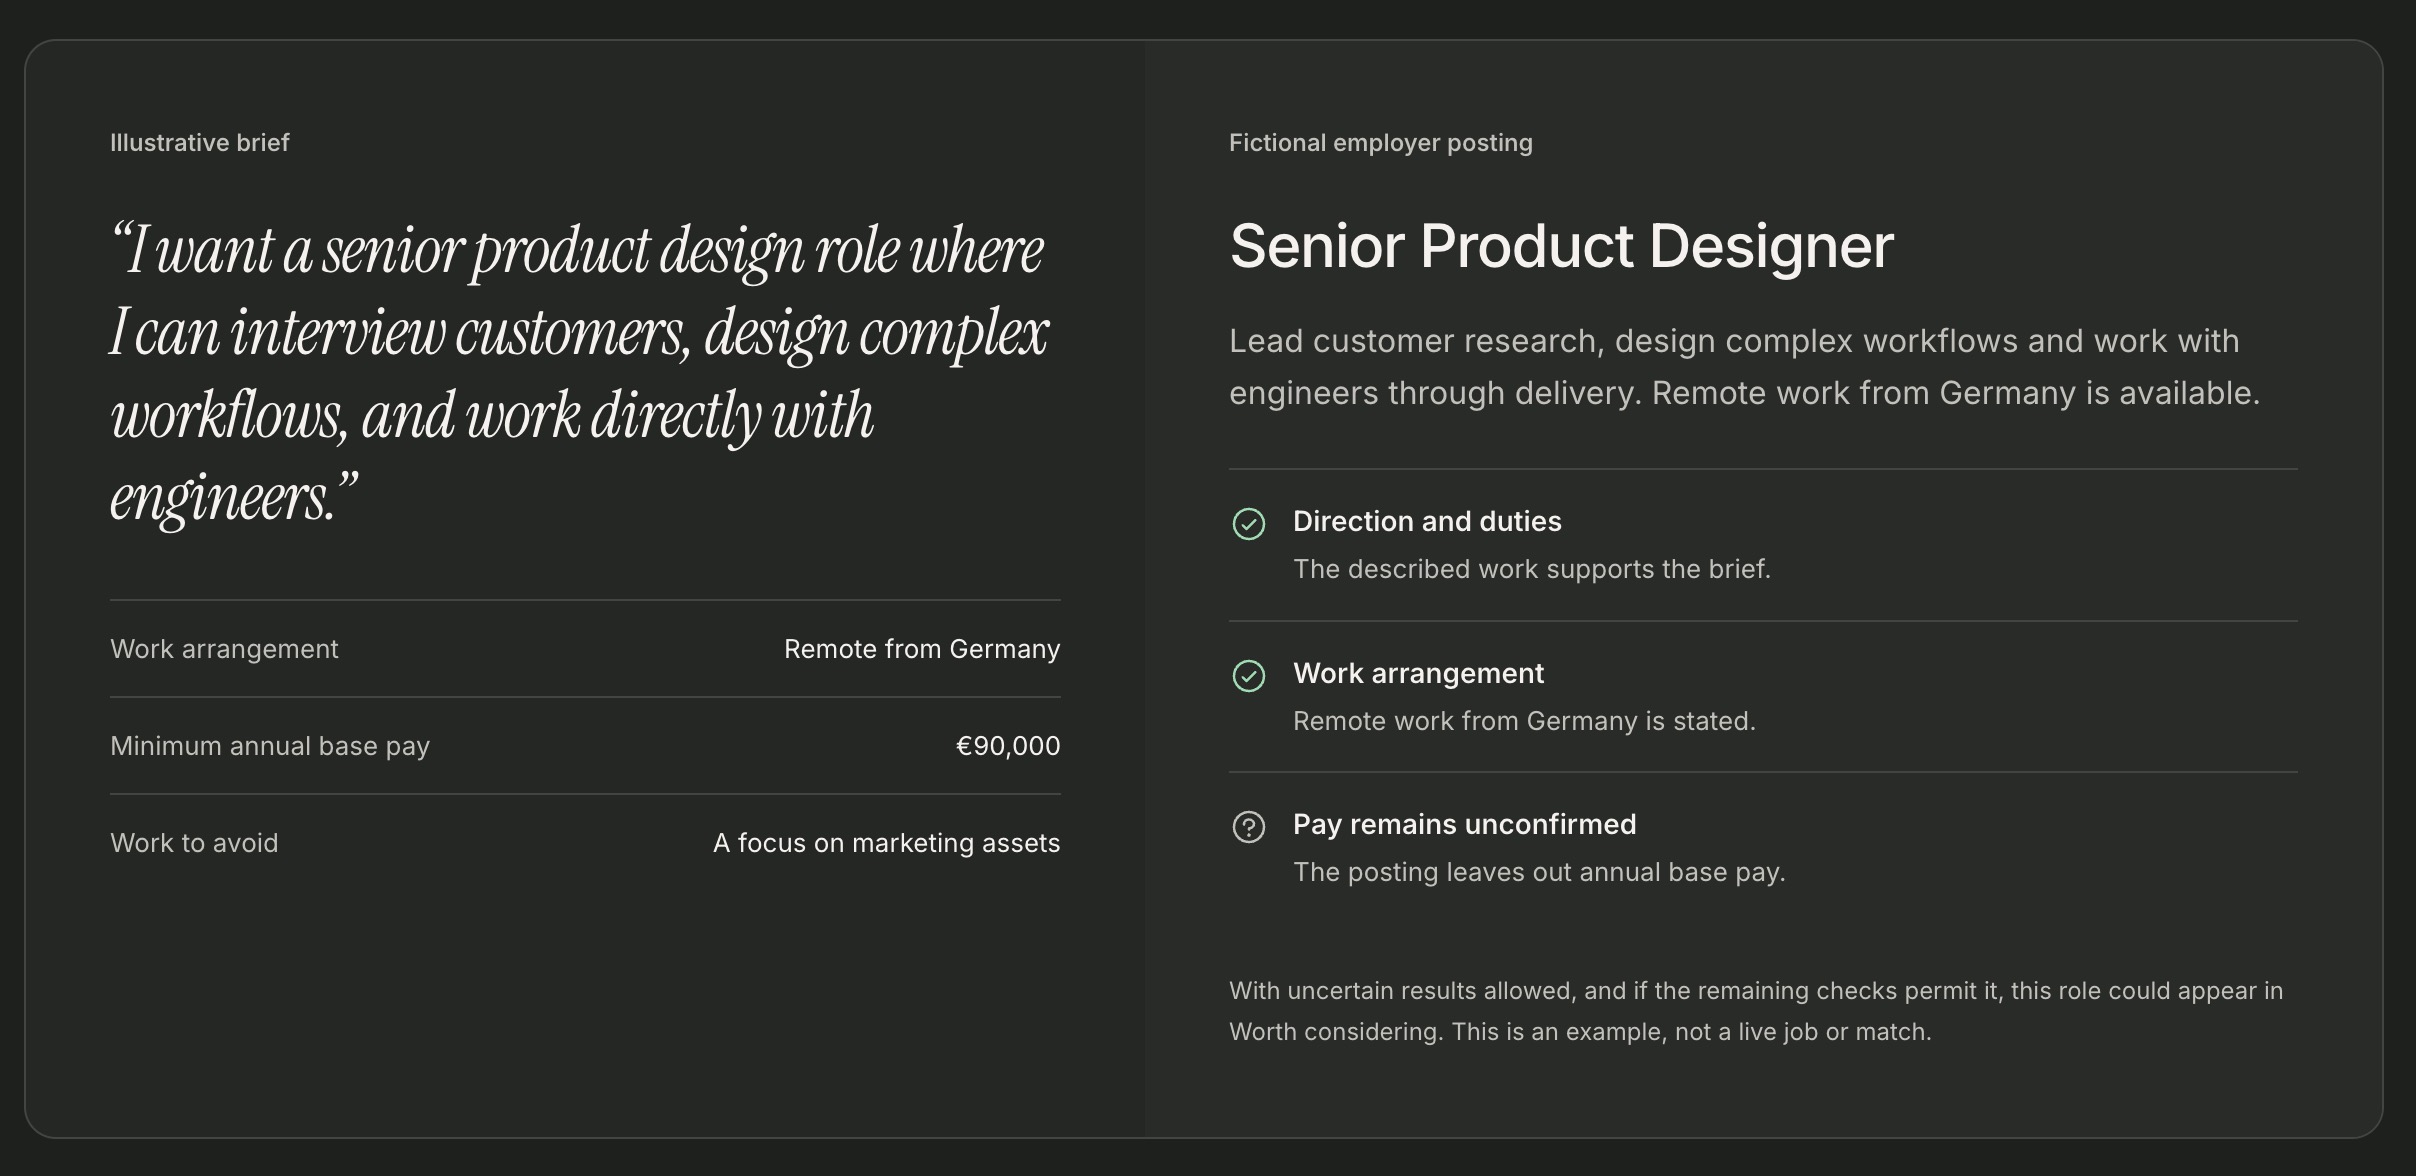
They want to interview customers, design complex workflows and work directly with engineers. They want to work remotely from Germany, earn at least €90,000 in annual base pay, and avoid a role focused on marketing assets.
Two postings can both say “Senior Product Designer” and describe very different jobs.
One might involve customer research and complicated software. Another might mostly involve campaign pages, sales decks and brand assets. Matching the title gets both into the same bucket. The person’s brief gives us a reason to separate them.
And if that person wants to change direction, matching them to their previous role can send them straight back to the work they want to leave.
Ping asks about the next role explicitly. The career background supplies context. The brief supplies the direction.
What I give Jev
Jev is TypeSafe’s decision model. You give it state and focused questions. It returns typed decisions and probabilities, rather than writing an explanation.
For matching, I use its Choice primitive. The state contains the person’s career context, their desired direction and duties, their exclusions and preferences, and the employer’s posting.
I ask separate questions about role direction, day-to-day work and seniority. If the person has named work to avoid, I ask about that too. Configured soft preferences get their own questions.
Each question has defined choices and criteria. Alignment can be CONFLICT, WEAK, ALIGNED, STRONG or UNKNOWN. Exclusions have their own CONFLICT, CLEAR and UNKNOWN choices.
That gives the application something specific to work with. A role can support the desired direction while describing duties that conflict with the brief. I can keep both judgements visible.
Jev returns a probability for each choice and a confidence value. I validate the response and map ambiguous answers to UNKNOWN. Those probabilities still need evaluation against real job-and-brief pairs. A confident answer can be wrong.
How the system fits together
I built the app with TanStack Start and React on Cloudflare Workers. A separate Worker handles scheduled and queued pipeline work. Neon Postgres stores postings, saved briefs, evaluations and results. Jev runs through the Cloudflare AI binding and AI Gateway.
Employer sources are verified before ingestion. The collectors support systems such as Greenhouse, Lever, Ashby and Workday, plus supported employer pages with structured job data. I collect postings into a shared inventory, then retrieve a bounded shortlist for each brief.
Jev judges that shortlist. The source collection, search, numeric checks and recommendation rules remain ordinary software.
- CodeCollect and retrieveVerified sources, stored postings, a bounded shortlist and hard-requirement prefilters.
- JevJudge the workDirection, duties, seniority, exclusions and soft preferences, with uncertainty.
- CodeApply the policyHard requirements, match category, freshness and separate alert permissions.
- YouReview the evidenceRead the posting, inspect the fit, save a role and decide whether to apply.
I also keep immutable versions of the job, career profile and brief used for each evaluation. When someone reviews a result, the system can show which posting and which preferences produced it.
That is a large part of the build. A model response needs a place in a system that stores evidence, handles retries and knows when a result has become stale. A failed inference call stays an operational failure to handle; it does not silently become a rejected job.
A good fit cannot fill in missing pay
In the fictional design example, the employer describes the desired work and explicitly allows remote work from Germany. It leaves out salary.
The role might be worth considering. It cannot become a fully confirmed strong match on that evidence.
Code checks hard requirements using PASS, FAIL and UNKNOWN. A confirmed salary below the person’s minimum fails. Missing salary stays unknown. Strong alignment on the work cannot compensate for a failed requirement.
The strongest recommendation category requires every hard requirement to pass, strong alignment on both direction and duties, suitable seniority, clear exclusions and resolved soft preferences. Other eligible cases can be worth considering. If the person excludes uncertain results, unknown hard requirements keep the role out too.
The explanation in the interface comes from these stored judgements, checks and source evidence. Jev does not write a persuasive story about why the role must be right for you.
Why the obvious LLM approaches would have been weaker
I could have put the brief and posting into a single prompt and asked for a match score, a recommendation and a reason.
That would give me a very different product. One answer would have to carry several decisions: whether the work fits, whether the requirements pass, how much is unknown and whether the result deserves an alert. A polished explanation could make that answer feel more settled than the evidence allows.
I could also have used similarity to find jobs resembling someone’s CV, then asked an LLM to explain them. But resemblance to past experience does not establish support for the person’s desired next move. And a single score makes it harder to see which requirement failed.
| Approach | What happens to the evidence |
|---|---|
| One prompt picks and explains | Fit, eligibility and uncertainty can collapse into a recommendation and its justification. |
| CV similarity, then an LLM explanation | Resemblance can dominate retrieval. The explanation does not establish fit with the desired future work. |
| Jev judgements, explicit policy | Each semantic dimension stays separate. Code preserves unknowns, enforces requirements and controls actions. |
You can build a careful system with an LLM too. Structured outputs, focused questions, explicit rules and caching all help. I am not claiming that every LLM implementation would lose to Jev.
For me, Jev makes the decision interface the starting point. I can define the judgements the product needs and build around their outputs. The obvious all-in-one LLM versions would have hidden exactly the distinctions I want Ping to expose.
The same judgement should not be paid for twice
Once I had separated semantic judgement from policy, I could cache them separately too.
Opening or refreshing Matches reads stored results. It does not ask Jev to reconsider every role. New inference happens through an explicit check or the separately gated background pipeline.
The private inference cache keys the exact evidence, questions and requested model for each user. Changing a salary floor can recalculate eligibility without asking Jev whether the same duties still fit. Changing the desired duties or posting text changes the evidence and requires a new judgement.
- Open Matches again
- Read the saved evaluation. No new inference.
- Change only the salary minimum
- Reuse the semantic answers if their evidence is unchanged. Recheck eligibility in code.
- Change desired work or posting text
- Ask Jev again using the new evidence.
- Change the decision policy
- Revalidate stored raw answers and apply the current rules.
The raw-answer cache expires after 30 days. Database leases prevent a web request and a queue worker from paying for the same inference concurrently. Failed or malformed responses never become successful cache entries.
Caching is not unique to Jev. Keeping the model’s judgement separate from the application’s decision makes it clear what can be reused.
I use an LLM where I need writing
The application CV workflow uses the same division of work.
Jev first judges which supplied CV facts are relevant to the role. Qwen drafts wording from the ranked facts. Then Jev checks whether each proposed claim is supported by the CV facts it cites.
The writer receives the target role title and selected CV evidence, rather than the full employer posting. The final check receives the proposed claim and its cited facts, without the job’s requirements or drafting instructions.
- JevRank relevanceJudge supplied CV facts against the role. Code orders the evidence.
- QwenDraft wordingPropose a profile and bullet rewrites from the supplied facts.
- Jev + codeCheck supportTest claims against cited facts. Keep original wording when support is uncertain or missing.
Code also rejects invented numbers. Unsupported or uncertain bullet rewrites fall back to their original wording; a failed profile check keeps the original profile. The person can review and edit the accepted suggestions before applying on the employer’s website.
A generator alone would have left that workflow incomplete. I need decisions about relevance and factual support as well as words that read well. Jev gives me those checks, with conservative rules around what the product accepts.
What I still need to prove
When I wrote Jev made me rethink AI Ops Engineering, I was still early with it. Pingjobs gave me a concrete system to build around that idea.
The implementation and integration rehearsals establish that the pieces can work together. They do not establish recommendation quality. I still need independently labelled job-and-brief pairs, comparison against the same retrieval without Jev, and a complete deployed alert journey. Automatic scouting and alerts remain gated while those checks are outstanding.
I can explain why Jev made this architecture practical for me without pretending I have proved that it beats every other model.
I want Ping to find work that supports someone’s next move, show the evidence, keep missing facts visible, and respect the requirements they gave it. Jev lets me build the judgement layer for that product. The next test is whether real people find the resulting roles worth their attention.